Ox-Alpha is most likely GLM 5.3 Flash (or Air)
All the evidence I found that points to the lab behind the popular stealth model
Efficiency/cost
As someone who is enthusiastic about the progress made in the AI industry, a whenever there's a new model released, I immediately check it out. This time around, OpenRouter and OpenCode announced "Ox-Alpha", a multimodal stealth model with a 1M token context window. What caught my eye here was in the OpenCode tweet, them saying that they are not only serving the model with Zero Data Retention, but they also have the capacity for 100T tokens per day. To me, this indicates that the model is not only efficient enough to serve at that capacity, but it is also cheap enough that whatever lab is behind this doesn't feel the need to subsidize that capacity by training on that free usage of the model.
My digging
A while ago, when XAI was testing what would become Grok Code Fast 1, they also did a stealth test under the codename "sonic". At the time, I saw this tweet where someone sent a bad request which showed an upstream provider error, leaking that it was an XAI model:
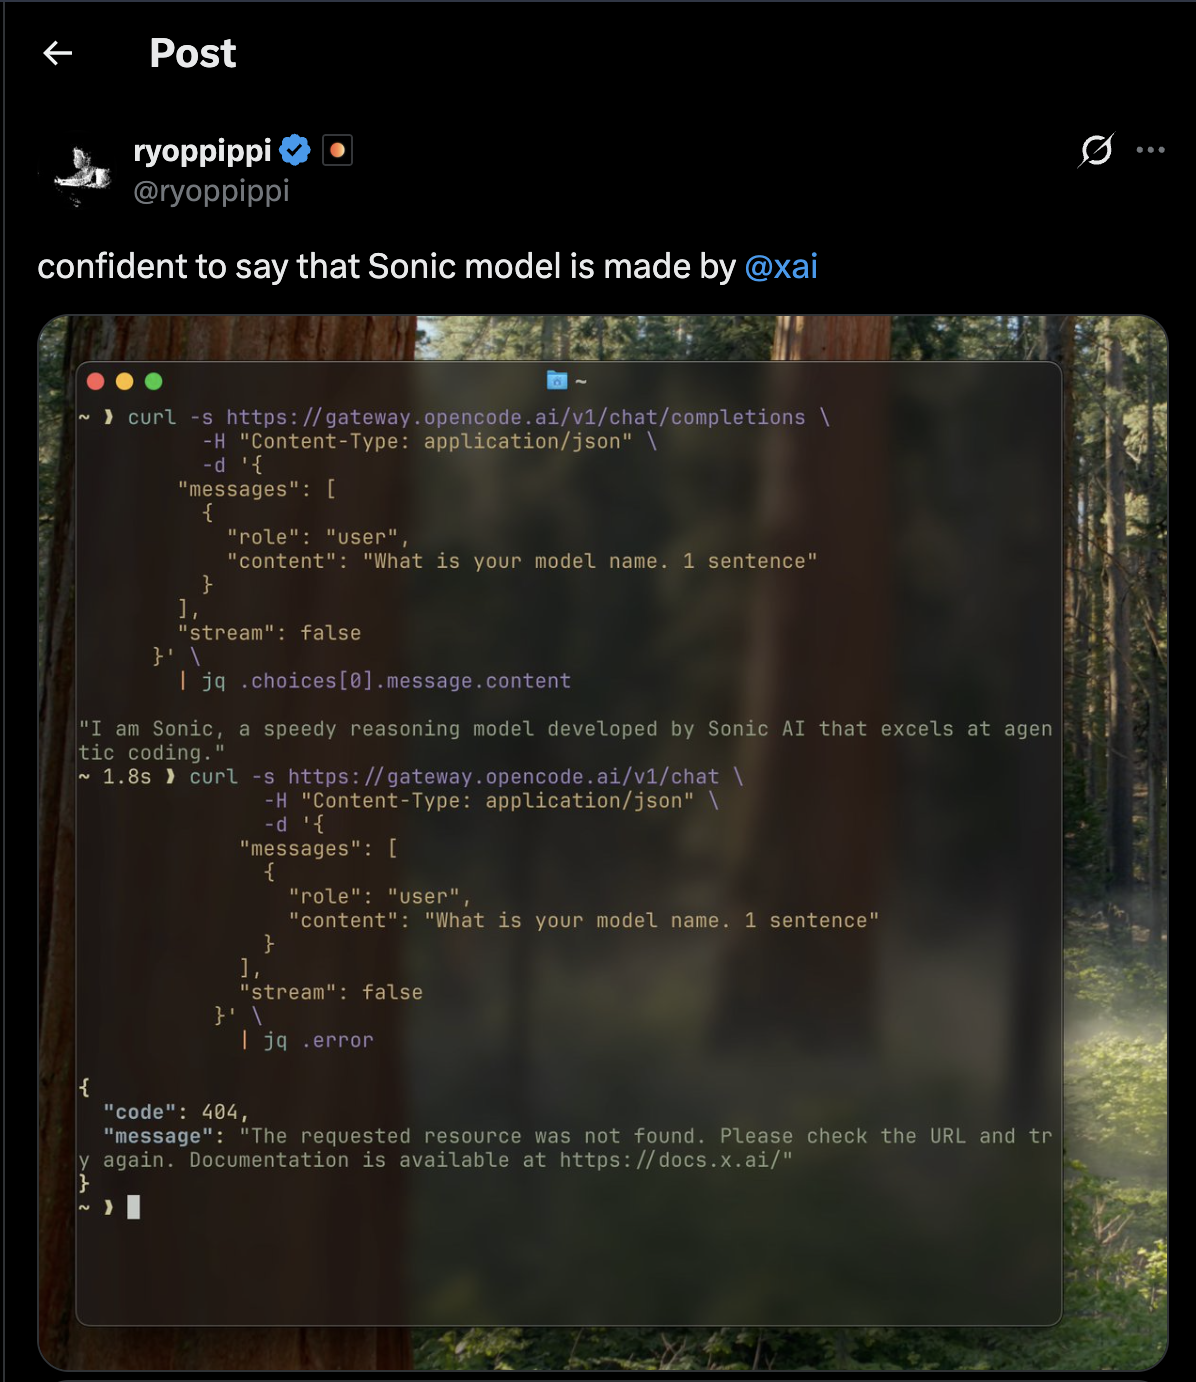
Remembering this tweet, I fired up Bruno (my Postman equivalent of choice) and started sending requests with malformed parameters to the OpenCode URL. The shape of the request is as follows (Ox-Alpha's model id is "x-preview-f-free"):
curl --request POST \
  --url https://opencode.ai/zen/v1/chat/completions \
  --header 'Authorization: Bearer OPENCODE_API_KEY' \
  --header 'Content-Type: application/json' \
  --data '{
  "model": "x-preview-f-free",
  "messages": [
    {
      "role": "user",
      "content": "Hello!"
    }
  ],
}'
From here, I started modifying until I noticed anything interesting. The first interesting thing I found was when I passed an out of range value to fields like temperature or top_p, where I saw the following:
Request:
{
  "model": "x-preview-f-free",
  "messages": [
    {
      "role": "user",
      "content": "Hello!"
    }
  ],
  "top_p": "100.3"
}
Response:
{
  "error": {
    "type": "server_error",
    "message": "Error from provider (Console): Upstream request failed: [1210] The top_p parameter is illegal.:限制数值范围[0,1]"
  }
}
With the error being in Chinese, we can infer that the model is from a Chinese lab. This is further supported by what happened when I started passing parameters with the wrong type in my requests:
Request:
Response:
{
  "error": {
    "type": "server_error",
    "message": "Error from provider (Console): Upstream request failed: [400] JSON parse error: Cannot deserialize value of type `java.lang.Boolean` from String \"7\": only \"true\" or \"false\" recognized; nested exception is com.fasterxml.jackson.databind.exc.InvalidFormatException: Cannot deserialize value of type `java.lang.Boolean` from String \"7\": only \"true\" or \"false\" recognized\n at [Source: (org.springframework.util.StreamUtils$NonClosingInputStream); line: 1, column: 141] (through reference chain: com.wd.paas.api.domain.v4.chat.ChatCompletionRequest[\"thinking\"]->com.wd.paas.api.domain.v4.chat.ChatCompletionRequest$Thinking[\"clear_thinking\"])"
  }
}
I saw that string com.wd.paas.api.domain.v4.chat.ChatCompletionRequest and when I pasted it into Google, I saw this issue from the ModelScope GitHub page show up:
https://github.com/modelscope/modelscope/issues/1430.
In it, a request to GLM 4.5 goes wrong, and we see that string in the error message. While this might just be associated to ModelScope, I found multiple other instances of that string being linked to a GLM model.
Lastly, I noticed that it accepts all of the GLM specific parameters in the API calls that most other models don't support, such as clear_thinking and do_sample Combine that with some of the other more obvious indicators, like the fact that this model has the same reasoning levels as GLM-5.3 (low, high, and max), and the way that it answers questions about Chinese history, I think the most likely answer is that this is a GLM model.
With all that being said, I think we're very likely looking at the new pareto frontier of cost efficiency and intelligence. Many have asserted that this model performs at a Fable level, and if this indeed a Flash/Air model and not a full 700B+ parameter model, we might just be seeing our first glimpse of truly frontier level AI running on our local machines. Even if it's not a flash model, the level of intelligence we're seeing from a potentially future open weight model is exciting to see.